Most AI tools run in someone else’s cloud. For a bank, a fund, a health system, or a law firm, that is where the trouble starts, because each prompt can carry regulated data out of the network the firm has to protect.
This guide explains private AI in plain terms. It covers what the term means, whether the models can run on your own servers, why cloud AI causes problems for a regulated firm, and what changes when the AI runs inside your walls.
What does private AI mean?
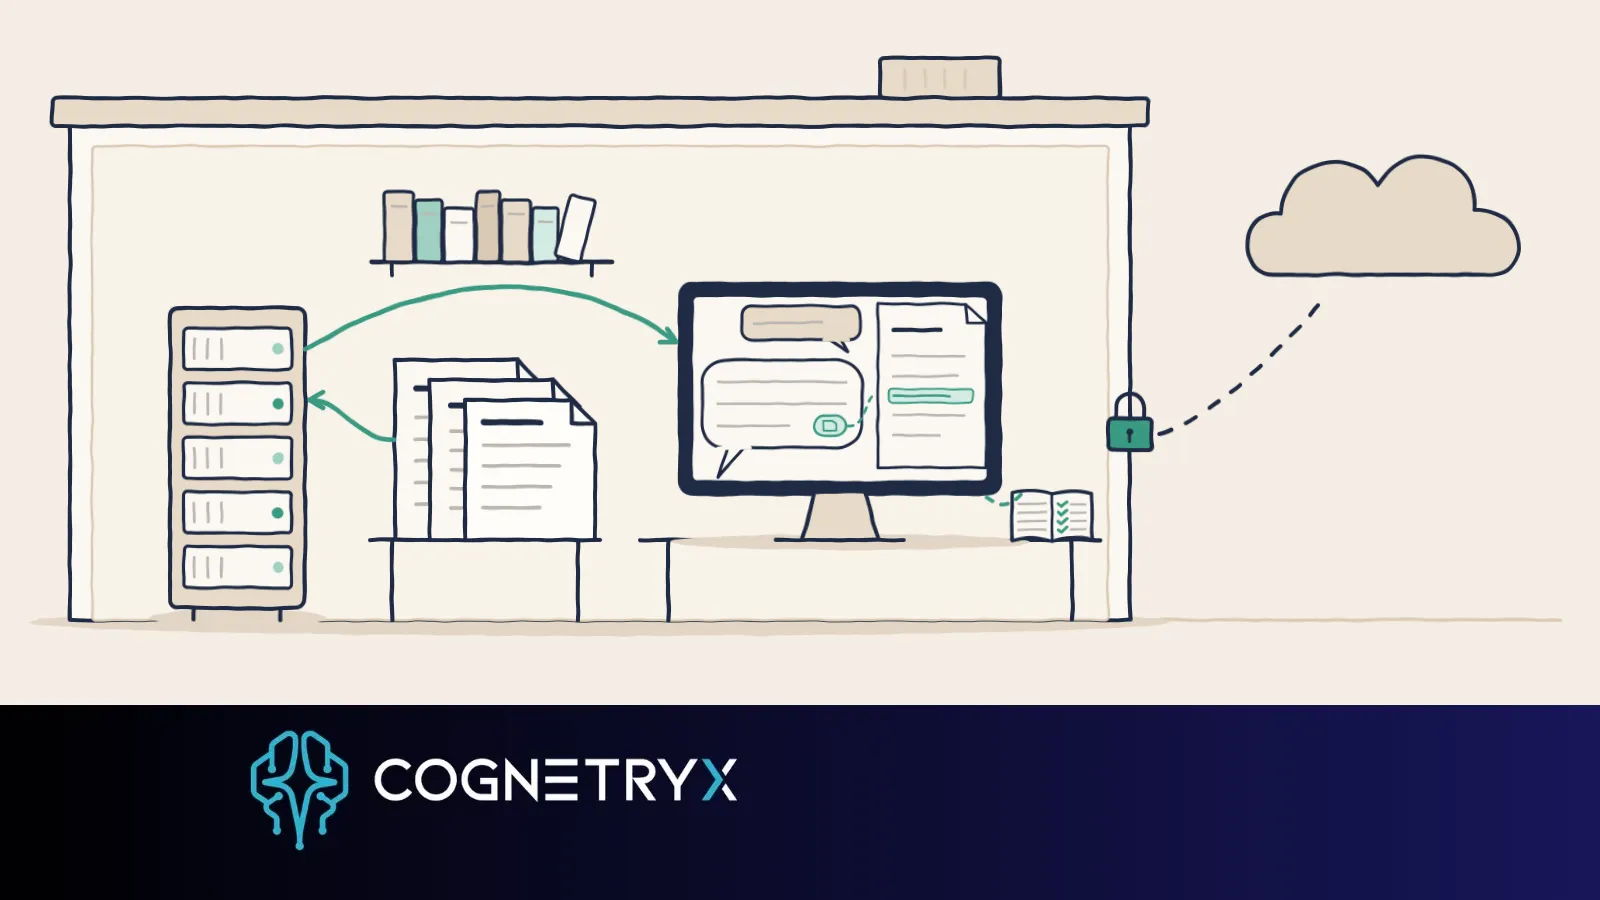
Private AI runs inside your own environment. The model, the documents it reads, and the record of what it did all stay inside the network you control, so a question gets answered without your data leaving your walls.
Four related terms come up often.
On-premises AI runs on hardware you control, in your own data center or a private environment you operate.
A private LLM is a large language model served inside your environment. Staff reach it over your own network.
Air-gapped AI has no connection to outside networks at all. It is used for classified defense work and for some of the most sensitive systems in finance and health care.
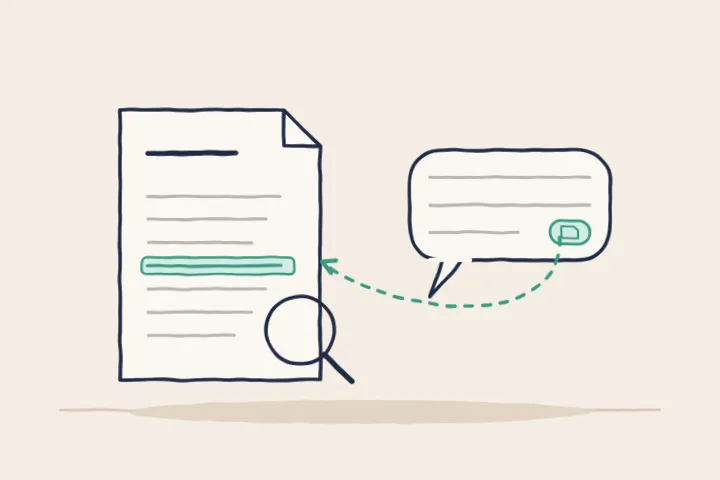
Grounded retrieval means the AI answers from your approved documents and shows where each answer came from.
All four describe control. Your data stays where you can account for it, and you can show an examiner what the system read and why it answered the way it did.
Can AI models run on your own servers?
Yes. Open-weight large language models, such as Meta’s Llama family, run on hardware you own, inside your own network, and answer without calling an outside AI vendor. Most of the work goes into the layers around the model.
A model on its own answers from what it learned in training. To be useful at a bank, it also has to find the current policy, respect who may open which file, and keep a record an auditor can read a year later. Retrieval, access control, and audit are what separate a working private AI system from a pilot that stays in the lab.
Our guide to the private AI stack you’d build yourself covers the parts, where the servers can run, and what sets the timeline.
Why is cloud AI a problem for a regulated firm?
Sending text to a cloud AI service and reading back the answer is the easy way to start. For a regulated firm, it creates three problems at once: the data leaves your network, staff use AI tools you haven’t approved, and examiners ask questions a cloud model makes hard to answer.
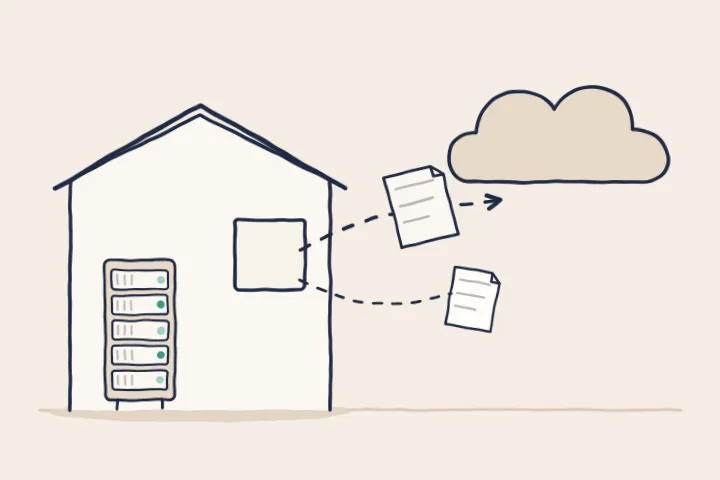
Your data leaves the network you answer for
Once a prompt reaches an outside AI service, regulated data is in someone else’s systems. That pulls the vendor into your duties for vendor oversight, breach response, and data residency. A contract governs how the vendor handles the data, and the data itself is now outside your walls. When a breach does happen, the bill is large. IBM’s 2026 study put the average breach at a record $4.99 million worldwide and $11.5 million in the United States. Financial services had the second-costliest breaches after health care, at $6.29 million.[1]
Staff already use AI tools outside your view
While leadership writes the policy, employees paste real work into whatever AI tool is open in a browser tab. IBM calls this shadow AI. In IBM’s 2026 study of 602 breached organizations, 43% reported a security incident involving shadow AI, up from 20% a year earlier. Among those whose breach involved an AI model or app, 92% lacked proper AI access controls.[1] Governance starts with AI your firm runs itself.
Examiners ask questions a cloud model makes hard to answer
An examiner asks where the data went, who could see it, whether you can reproduce a result, and whether you can prove each of those. When someone else controls the model’s version and behavior, those answers are harder to give with confidence. Privacy worries run high, too. In Cloudera’s 2025 survey of nearly 1,500 IT leaders in 14 countries, 53% named data privacy as a barrier to adopting AI agents, more than any other barrier.[2]
What changes when AI runs inside your network?
Moving the model inside your walls changes what you can answer for. Records stay inside the boundary you already protect, access follows your own role rules, every answer can be traced to its source and logged, and your firm decides when the model changes.
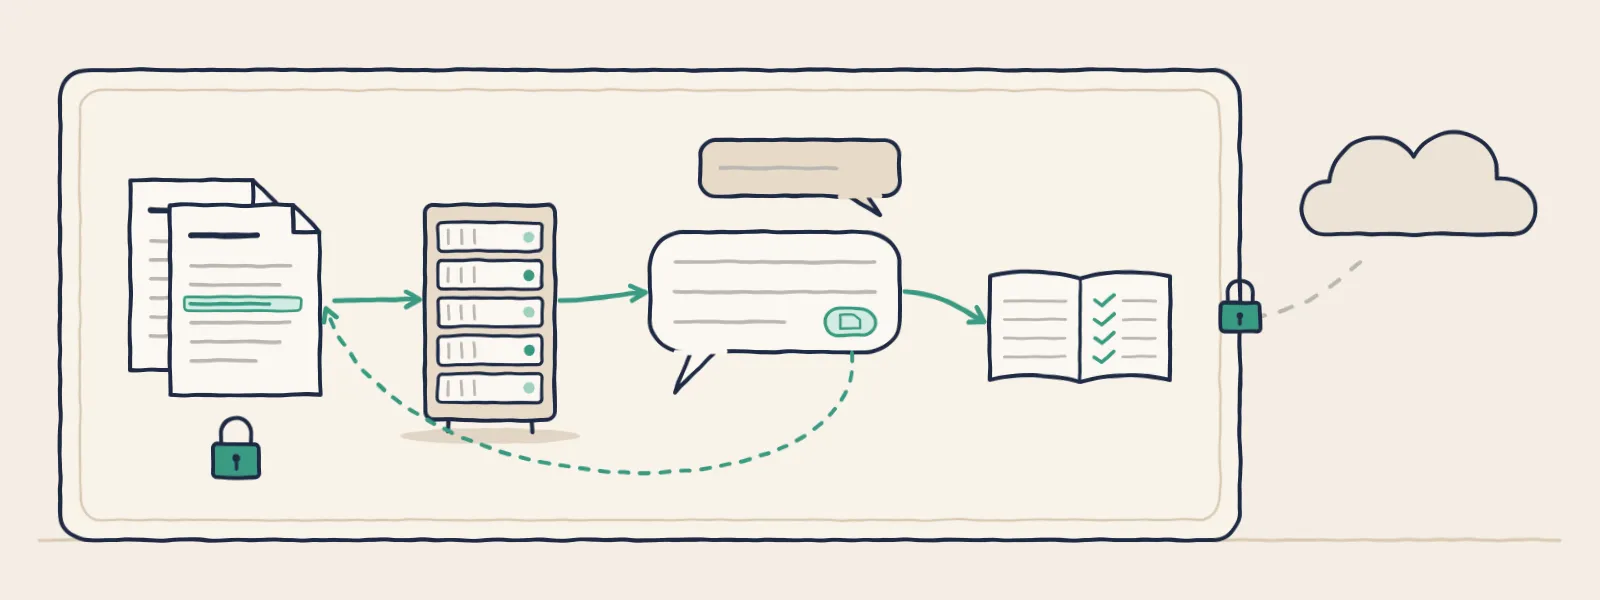
- Regulated records stay inside the boundary you already protect, with no new path for data to leave.
- Every question, answer, and source the system used can be logged where you keep your other records. That record is what audits and exams ask for.
- Access follows your own identity and role rules, so people see what they are cleared to see.
- Answers come from your approved documents and cite their source, so staff can check them.
- You decide when the model changes, so an outside update can’t undo work you already validated.
Where the AI runs decides much of what a regulated firm can prove. Policies and validation reports build on that choice. Why Cognetryx shows how Lumen, our platform, handles each point, and How It Works walks through it.
Why do so many AI projects stall?
An MIT NANDA report from July 2025 found that 95% of organizations were getting zero return on their generative AI spending.[3] The authors trace most stalls to a learning gap. Most tools don’t learn from feedback, keep context, or fit into daily work.
That matches what regulated firms see. People use AI they can check, working from the firm’s own documents inside the work they already do. The setup that satisfies an examiner is also the one that makes the tool worth using.
Where does private AI stand in 2026?
In NTT DATA’s 2026 research, 95% of organizations said private and sovereign AI are important, yet only 29% are making sovereign AI a near-term priority.[4] Nearly 60% of the companies NTT DATA ranks as AI leaders say limits on moving data across borders are a major challenge. Demand is real, and deployment trails it.
How does it differ by industry?
The case plays out a little differently in each regulated field, because each one has its own rules and its own examiners. See how it applies to banks and credit unions, health care, law firms, government and defense, and manufacturing.
See private AI answer from your own documents
Bring a policy or a loan file to a 30-minute demo and check each answer against its source.
See it in actionSources
- IBM, Cost of a Data Breach Report 2026, released July 29, 2026. The Ponemon Institute ran the study for IBM, covering 602 organizations breached between March 2025 and February 2026. Average breach cost of $4.99 million worldwide and $11.5 million in the U.S.; health care costliest at $6.64 million and financial services next at $6.29 million; 43% of the organizations reported an incident involving shadow AI (20% in 2025); 21% had a breach involving an AI model or application, and 92% of those lacked proper AI access controls. newsroom.ibm.com; ibm.com/reports/data-breach
- Cloudera, press release on its survey The Future of Enterprise AI Agents, April 16, 2025. Nearly 1,500 enterprise IT leaders in 14 countries. Data privacy was the barrier named most often (53%), ahead of integration with legacy systems (40%) and cost (39%); respondents could name more than one. cloudera.com
- MIT NANDA (Challapally, Pease, Raskar, and Chari), The GenAI Divide: State of AI in Business 2025, July 2025, preliminary findings. Based on a review of more than 300 public AI projects, interviews with 52 organizations, and a survey of 153 senior leaders. report (PDF)
- NTT DATA, 2026 Global AI Report: A Playbook for Private and Sovereign AI, released May 14, 2026. Two online surveys from September and October 2025: 2,567 AI decision-makers and 2,335 technology decision-makers, with fieldwork by STRAT7 Jigsaw. us.nttdata.com
This article is informational and not legal or compliance advice. Confirm how any rule applies to your firm with your own counsel and compliance team.