Ask an AI assistant when a SAR is due and you get a date from the rule: 30 calendar days after the bank first detects facts that may call for one, or up to 60 if no suspect has been identified.[1] Ask whether a run of cash deposits is suspicious and you get an answer in the same voice. The first question has one right answer. The second is a judgment the rule leaves to your bank, and the tool made it for you without saying so.
Both answers read well, and both cite real rules. Nothing in the output tells you which kind of question you asked. Citation checks pass, since every source is real, so this failure gets past the controls built to catch wrong answers.
What is the difference between a wrong answer and a judgment made for you?
A wrong answer is a false claim about something with a knowable answer, such as a misquoted retention period or a rule pinned on the wrong agency. Open the source, compare, and the error shows. A judgment made for you contains no false claim. Every source is real and the logic holds, yet the answer is one fair position among several.
The two failures need different controls. Checking citations catches the first, and we cover how in how to check an AI answer before it reaches an examiner. Citation checks do nothing for the second, because nothing in the answer is false. The tool made a choice and left it out of the reply.
Which rules in banking and investing leave the call to you?
Any rule built on words like reasonable, suspect, material, or appropriate. Rule writers pick those words on purpose. A fixed number would be gamed, or would fail cases no one foresaw, so the rule hands the call to the firm and expects the firm to defend it.
The FFIEC's BSA/AML exam manual says it in one line: "The decision to file a SAR is an inherently subjective judgment."[2]
Under the Bank Secrecy Act rules, a bank must report a transaction of $5,000 or more when it "knows, suspects, or has reason to suspect" certain things. One of them is that the transaction "has no business or apparent lawful purpose or is not the sort in which the particular customer would normally be expected to engage," and the bank knows of no reasonable explanation after looking at the facts.[1] Reason to suspect is a call an experienced analyst makes and writes down.
The SEC's amended Reg S-P adds a newer one for brokers, funds, advisers, and transfer agents. After unauthorized access to sensitive customer information, the firm must notify each affected person unless, "after a reasonable investigation," it decides the information "has not been, and is not reasonably likely to be, used in a manner that would result in substantial harm or inconvenience."[3] Every covered firm had to comply by June 3, 2026.[4] That one sentence holds three judgment calls: what counts as a reasonable investigation, what is reasonably likely, and what counts as substantial harm.
In daily work, these questions arrive looking like lookups:
| The question a user types | What it looks like | What it actually is |
|---|---|---|
| "Is this run of cash deposits suspicious?" | A sorting task | A reason-to-suspect call the bank owns and must defend |
| "Do we have to tell clients about this breach?" | A policy lookup | A Reg S-P harm judgment the firm owns |
| "Is this information material?" | A threshold check | A weighing of facts with no single right number |
| "Does this position break the issuer limit in our investment policy?" | A policy lookup | A policy lookup. The limit is a number in a document, so anyone can check the answer. |
A user asking the left column thinks they are asking the middle one, and the tool answers as if they were. The last row is the kind of question AI handles well, because the answer is a number in a document that anyone can check.
Why does AI sound just as sure either way?
Because the way models are tuned rewards sounding sure. Models learn from people's ratings of their answers. A 2024 study of that tuning found the reward models it relies on favor confident answers regardless of quality, and the tuned models state more confidence than their answers earn.[5]
A 2025 study by Junchen Ding and colleagues shows what that looks like on questions with no right answer. The team gave 14 leading models 27 trolley-problem scenarios under ten moral framings and collected 3,780 yes-or-no decisions with written reasons.[6] Choices varied a lot across framings and across types of model. Models built for step-by-step reasoning were more decisive and gave neater reasons, yet they did not always line up better with human consensus.
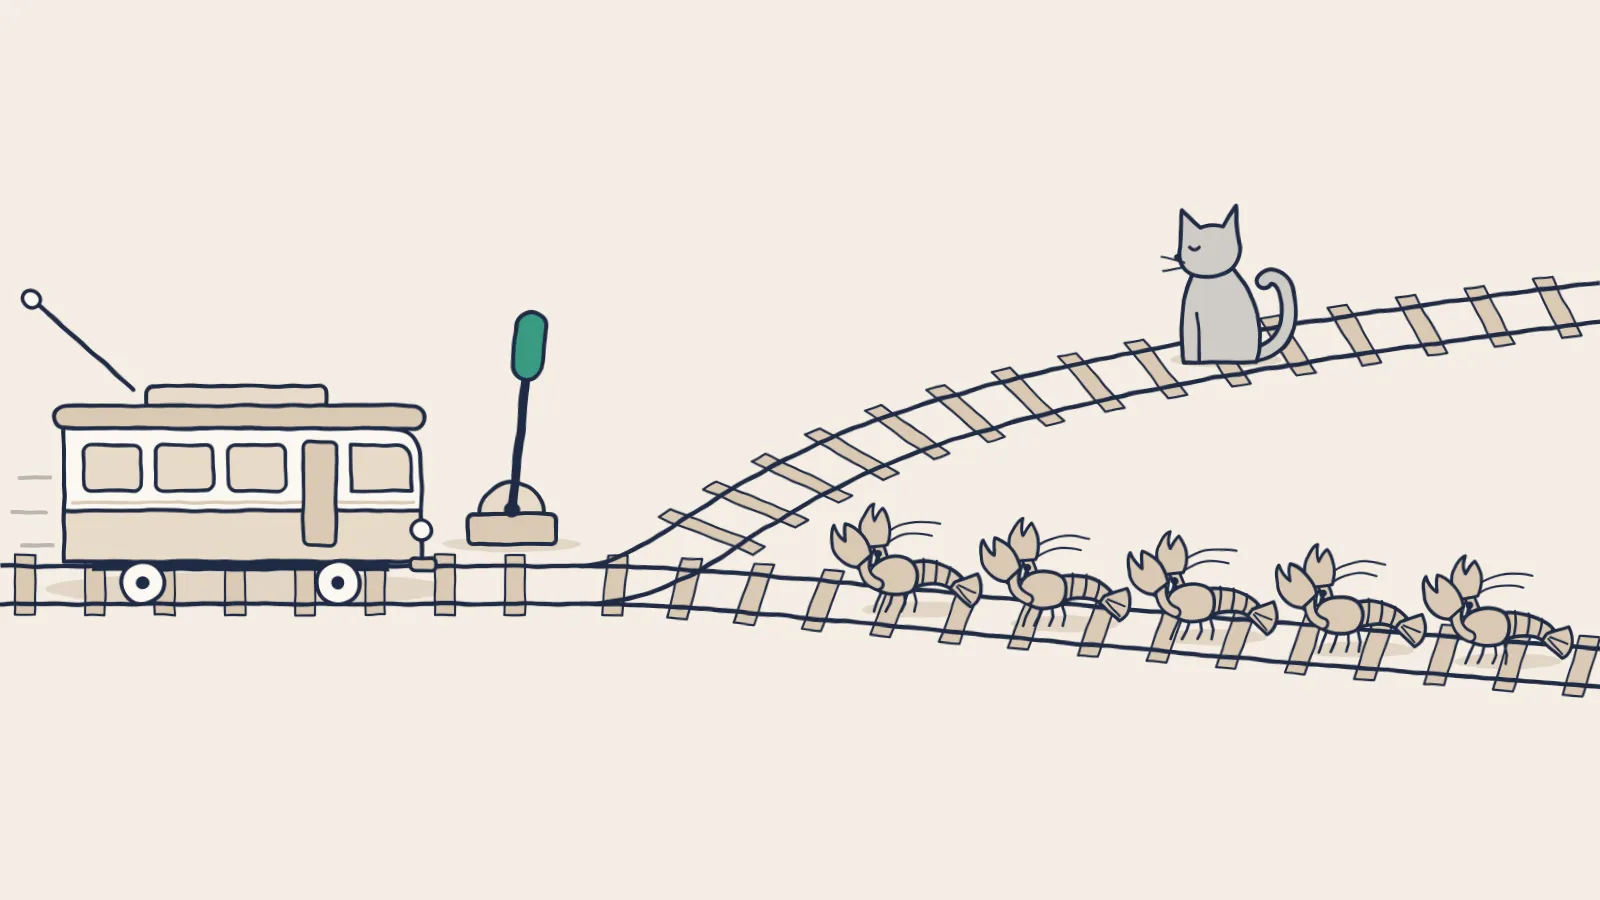
Our cover image comes from a level of Neal Agarwal's Absurd Trolley Problems, with five lobsters on one track and a cat on the other. Count lives and you save the lobsters. Weigh how much each animal can suffer and you may save the cat. Both answers come from the same school of ethics with different inputs. We walked through the level on LinkedIn. Lobsters are a joke, but the voice that answers them is the same one you get when you ask whether a wire pattern needs a SAR.
Will a better model fix this?
A better model makes the answer more convincing. In the Ding study, the models built to reason better were the more decisive ones, with no reliable gain in agreement with people. Sounding sure comes from how models are trained to be useful, so build your controls around it and expect the next release to sound just as sure.
Check what your model risk program covers, too. On April 17, 2026, the Federal Reserve, the OCC, and the FDIC issued revised model risk guidance, SR 26-2, replacing SR 11-7. The OCC's bulletin on it says generative and agentic AI models "are not within the scope of this guidance."[7] A bank that mapped its AI assistant to its model risk framework now has to write those controls itself. We cover the exam side in bank and credit union exams in 2026.
What should the system around the model do?
Make the judgment visible and hand it to a person. If the model can't be trusted to flag a judgment call, the system around it has to. Three controls do most of that work, and each one gives an examiner something to test.
- A person approves before anything with consequences happens. An assistant that drafts a SAR narrative saves an analyst time. An agent that files one has made the call the rule gave to your bank. Put the approval step in front of the action and turn it on by default.
- A record that outlasts the people who made it. Keep the question, the answer, the passages the tool used, who asked, and who approved. A judgment call can't be rebuilt from its conclusion, because the conclusion never shows the options that were weighed.
- A log that the people and tools it records can't edit. An audit trail a privileged user can change proves little. Store it where the people and agents it records have no write access, and check that it stays complete.
Lumen, the private AI platform from Cognetryx, is built for this kind of review. Every answer cites its source, and clicking a citation opens the document with the passage highlighted, so a reviewer sees the exact words the tool relied on. Answers follow each person's existing permissions through SSO over SAML or OIDC, so the evidence behind an answer is evidence that person could already open. The Compliance Portal logs chats, tool calls, agent runs, approvals, and sign-ins, and your compliance team can search it. It all runs on your own servers.
The aim is a model whose part in a decision is visible and bounded, so a judgment call reaches a person before it reaches a filing.
How do you audit a judgment call months later?
You build the record before you need it. An examiner who asks why a SAR wasn't filed in March is asking about reasoning, and the reasoning has to exist somewhere lasting. The FFIEC manual tells examiners to focus on whether the bank has an effective SAR decision process, and they may review single decisions to test it.[2]
An AI tool in that process is one more participant whose reasoning has to be traceable. Our guide to BSA and AML decisions an examiner can follow covers the human side.
Questions to put to any vendor, and to your own team:
- When the tool answers a question that turns on a judgment standard, what in the answer tells the user so?
- Can a reviewer see the exact passages the tool used?
- Which actions can an agent take without a person approving them, and is approval on by default?
- Can someone with admin rights change the audit trail without it showing?
- Six months from now, can you show who approved what, and on what basis?
If the honest answer to the first question is "nothing," you want to learn that before an examiner does.
What does a good answer to a judgment question look like?
It reports its own footing. A good answer says what the policy says, marks the point where the rule calls for judgment, lays out the facts that pull each way, and names the person who owns the call. A tool that refuses every hard question is less useful than a search box, so refusal is the wrong goal.
Your best analysts already work this way. Ask a good one whether an account is suspicious and you get what they saw, what it looks like, what argues against it, and what they concluded and why. The conclusion is the least interesting part, because the reasoning is what gets examined.
Hold the software to the standard you already hold people to. An answer that says "it depends on these three facts" is the model telling you the truth about the question.
See answers you can check
Every answer links to the passage it came from, and chats, agent runs, and approvals are logged for your compliance team.
See it in actionSources
- 31 CFR 1020.320, Reports by banks of suspicious transactions. Paragraph (a)(2) sets when a report is required. Paragraph (b)(3) sets the 30-day filing deadline and the 60-day limit when no suspect has been identified. law.cornell.edu
- FFIEC BSA/AML Examination Manual, Suspicious Activity Reporting, Overview. See the part on SAR decision making. bsaaml.ffiec.gov
- 17 CFR 248.30(a)(4)(i), Regulation S-P, notice to affected individuals, as amended by the SEC in 2024. law.cornell.edu
- Securities and Exchange Commission, Regulation S-P final rule, 89 FR 47688, June 3, 2024. Section II.F gives larger entities 18 months and smaller entities 24 months to comply. federalregister.gov
- Jixuan Leng, Chengsong Huang, Banghua Zhu, and Jiaxin Huang, Taming Overconfidence in LLMs: Reward Calibration in RLHF, arXiv:2410.09724, October 2024. arxiv.org
- Junchen Ding and colleagues, Pull or Not to Pull? Investigating Moral Biases in Leading Large Language Models Across Ethical Dilemmas, arXiv:2508.07284, August 10, 2025. arxiv.org
- Office of the Comptroller of the Currency, Bulletin 2026-13, Model Risk Management: Revised Guidance, April 17, 2026, issued with the Federal Reserve and the FDIC. occ.gov
This article is informational and not legal or compliance advice. Confirm how any rule applies to your firm with your own counsel.