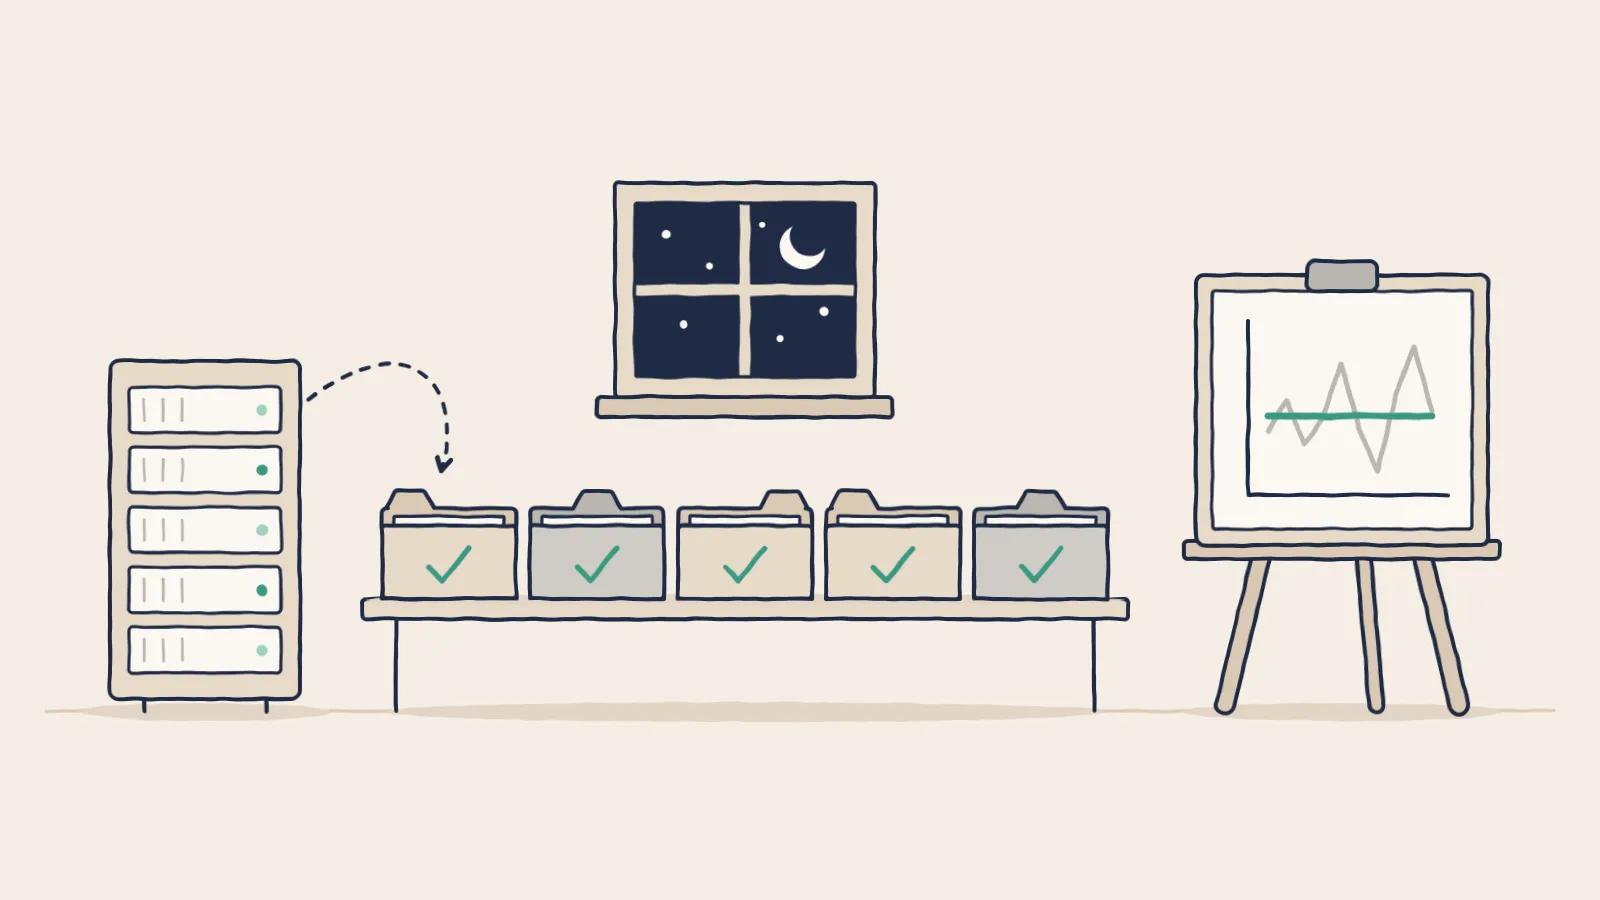
Picture an agent that opens every new loan file each night. It checks the file against the credit policy's list of required documents and leaves a note on each gap, so the processor starts the morning with a list of what to chase.
Put that agent on a per-token meter and someone will ask whether it needs to read every file. Maybe only the large ones. Maybe a sample. The meter shapes what you automate long before the invoice arrives.
A fixed cost takes that question away. The platform costs the same whether the agent reads a handful of files or all of them, and the limit becomes how much work your hardware can do in a night.
What is an AI token, and how is it priced?
A token is the unit an AI model reads and writes: a short piece of text, about three quarters of a word in English.[1] Cloud AI is priced per million tokens, with one rate for input, the text the model reads, and a higher rate for output, the text it writes.
OpenAI's rule of thumb is that a token is about four characters of English text.[1] Splitting text into tokens is called tokenization, and OpenAI's own example splits "tokenization" into "token" and "ization."[1] Payments and data security use the same word for something else: swapping a card or account number for a stand-in value.
Input covers your question, the model's instructions, and any documents pulled in to answer it. In September 2026, Anthropic listed its Claude Sonnet 5 model at $2 per million input tokens and $10 per million output tokens, and OpenAI listed gpt-6-sol at the same rates.[2][3] Reasoning models also work through a problem in hidden text before they answer, and OpenAI bills that text as output tokens.[4]
At those rates, one token costs a tiny fraction of a cent, so the bill comes from volume. At about 500 words a page, a 30-page policy is roughly 20,000 tokens. An agent that reads 500 of those files each night sends 10 million tokens, about $20 a night on input alone. Each extra step in the agent's loop sends that text again.
Why is a metered AI bill so hard to forecast?
Three things move at once. The same request can use a different number of tokens each time. Agents take more steps on some days than on others. And per-token prices fall while use climbs faster. In a 2026 survey by Mavvrik, which sells software to track AI costs, only 11% of 396 organizations forecast their AI spending to within 10%.[5]
The first swing comes from how the models work. Will Venters, who teaches information systems at the London School of Economics, told the BBC that because an AI's output varies, so does its cost.[6] Ask the same question on Tuesday and again on Thursday, and Thursday's answer may run longer, use more tokens, and cost more. Your policy and headcount stayed the same, and the bill still moved.
Agents add a second layer. Each step in an agent's loop sends text back to the model, so a task can take more steps this week than last if an early answer comes back different. Agents are also easy to add. As the BBC piece noted, you can employ more of them with the click of a button.[6]
Cheaper tokens have come with bigger bills. Ramp, the corporate card and finance software company, reported that among businesses with connected AI, token use grew 1,001% from January 2025 to April 2026. Total spending grew 497% over the same months, even as the price per token fell.[7]
Why does the work you automate get metered?
Agents earn their keep by working while nobody watches: checking files overnight, reviewing alerts, drafting first passes before the team arrives. That unattended work burns the most tokens, so vendors are putting their meters on it. Under a meter, the more useful the agent, the bigger the bill, and the harder next quarter is to predict.
GitHub said as much when it moved Copilot to usage-based billing on June 1, 2026. In announcing the change, it wrote that a quick chat question and a multi-hour autonomous coding session could cost the user the same amount.[8] Each plan now comes with a monthly allowance of credits, and use beyond it is billed by the token at each model's published rate.
The traffic points the same way. OpenRouter, a marketplace developers use to reach many AI models, marked February 6, 2026 as possibly the last day people used more tokens on its platform than agents did.[9]
The natural response is to ration. Teams cap the agent, sample the files, or run the job weekly, and the work you most wanted automated gets the least of it.
Your software vendors face the same problem one layer up. When they build AI into a product you already license, they buy tokens too, and they have to set your price before they know their own cost. Bill Peterson of Sumo Logic told the BBC that nobody has really figured out how to price agent-based services, and that customers dislike prices that change every couple of months.[6] Simon Gooch of Saviynt said tying a customer to a cost model for one to three years makes little sense, because vendors don't know their own costs that far ahead.
For a bank or a fund, that uncertainty flows straight into an annual budget the board approves, and into a third-party risk program that expects contracts with a knowable value.
When is the cloud meter the cheaper choice?
At low volume, usually. A per-token service costs nothing while it's idle, and it needs no GPUs or staff on your side. Owned hardware costs the same busy or idle, so a light, bursty workload leaves you paying for empty hours. A pilot, a small team, or a monthly report belongs on the meter.
The math turns when the work is steady and heavy. An agent that reads every file every night keeps the hardware busy, and each extra job adds little to the cost. A fair comparison counts the idle hours and the engineers on the owned side. Anyone who says owning always wins has left one of them out.
Smaller models move the line. A model that needs fewer GPUs costs less to own, so bounded jobs such as tagging, pulling fields, and policy answers pay back sooner on owned hardware. Our guide to bounded AI work on smaller models covers which jobs fit.
Cost is also only part of the choice for a regulated firm. A model on your own servers keeps loan files and customer data under the controls your security team already runs.
What changes when the cost is fixed?
The AI line becomes the hardware or cloud capacity, the software, and the people who run it. A team can triple its questions and the number holds. That lets you point an agent at every file, every night, and stop weighing each run against the tokens it will burn.
At a bank, credit union, or fund, jobs that suit a nightly schedule include:
- Reading each new regulatory bulletin and matching it to the policies it touches.
- Comparing every new vendor contract with your third-party risk checklist.
- Pulling the customer's history together for each BSA alert opened overnight, so the analyst starts with one page.
- Checking every DDQ answer in your library against current policy and flagging the ones that no longer match.
- Tagging and routing every document that arrives in a shared inbox.
In Lumen, the Cognetryx platform, agents run on a schedule or start from an email, an upload, a webhook, a Jira issue, or a Slack mention. The platform has one fixed price, quoted after a short scoping call. The fixed-cost section of Why Cognetryx explains how the price is set.
What a fixed cost buys, at any volume, is a number you can put in a board packet a year out and explain when a director asks how you got there.
There is a real trade, and you should price it in. You take on capacity planning. If you size the hardware for today and use triples, you buy more hardware, and that takes a purchase and some lead time. The swings move from your invoice to your hardware plan. We think that is the better place for them, because hardware plans are annual and boards already know how to read them.
If you keep a meter, what should the contract say?
Some tools will stay on a meter, and for light use that's fine. For those, write the swings into the contract so the budget has a ceiling. Ask for five terms at the next renewal, and log any vague answer as a risk in your vendor review.
- A ceiling on the annual cost. A per-token rate gives you the slope. Ask what the yearly figure can't exceed, and what happens when you reach it.
- Notice before prices change. Enough time to rebuild a budget or move a workflow, written into the contract.
- Your own usage data. Token use by team, by workflow, and over time, in a format you can load. You need it to forecast next year and explain last year.
- Renewal terms in writing. If the vendor's own costs rise before renewal, who absorbs the increase? Get the answer in the contract.
- A clear split of the swings. Per-seat pricing puts them on the vendor. Per-token pricing puts them on you. Outcome pricing splits them, depending on how the outcome is defined.
At renewal, ask what the rate does when the vendor's own costs move, and who agreed to absorb that. Then price the jobs you want to run on every file, every night, both ways.
Run AI on every file, every night
See how Lumen runs agents on real financial documents, for one fixed platform price.
See it in actionSources
- OpenAI, "Key concepts," OpenAI API documentation, viewed September 26, 2026. Source of the rule of thumb and the "tokenization" example. developers.openai.com
- Anthropic, "Pricing," Claude API prices per million tokens, viewed September 26, 2026. claude.com
- OpenAI, "Pricing," OpenAI API documentation, standard tier, viewed September 26, 2026. developers.openai.com
- OpenAI, "Reasoning models," OpenAI API documentation, viewed September 26, 2026. developers.openai.com
- Mavvrik, with Benchmarkit, 2026 State of AI Cost Governance Report, published July 29, 2026. A survey of 396 enterprise organizations in April and May 2026. Mavvrik sells AI cost management software. mavvrik.ai
- Joe Fay, "Tokenomics: Why making AI pay is tricky," BBC News, August 2026. Source of the remarks by Will Venters (London School of Economics), Bill Peterson (Sumo Logic), and Simon Gooch (Saviynt), and the line on adding agents. syndicated copy on aol.com
- Rafael Hajjar, Ramp, "How Much Do AI Tokens Cost Businesses? 2026 Spending Benchmarks," June 8, 2026. ramp.com
- Mario Rodriguez, GitHub, "GitHub Copilot is moving to usage-based billing," April 27, 2026. The change took effect June 1, 2026. github.blog
- OpenRouter data page, "Token consumption: humans vs. agents," August 11, 2026. openrouter.ai/data
This article is informational and not financial or procurement advice.